

table of contents
Indexing in SEO is defined as the process by which a search engine stores and organizes a web page in its database, making it eligible to appear in search results. Without indexing, your pages are invisible to Google, no matter how well written they are. This guide explains the SEO indexing process, why it matters, and what you can do to fix pages that are not getting indexed. Understanding what does indexing mean in SEO is the first step toward building real search visibility for your site.
What does indexing mean in SEO, and how does it work?
Indexing is the critical SEO milestone where a search engine, after crawling, stores and organizes a URL to appear in search results. Not every crawled page makes it into the index. Search engines apply quality filters, and pages that fail those filters simply do not show up in results.
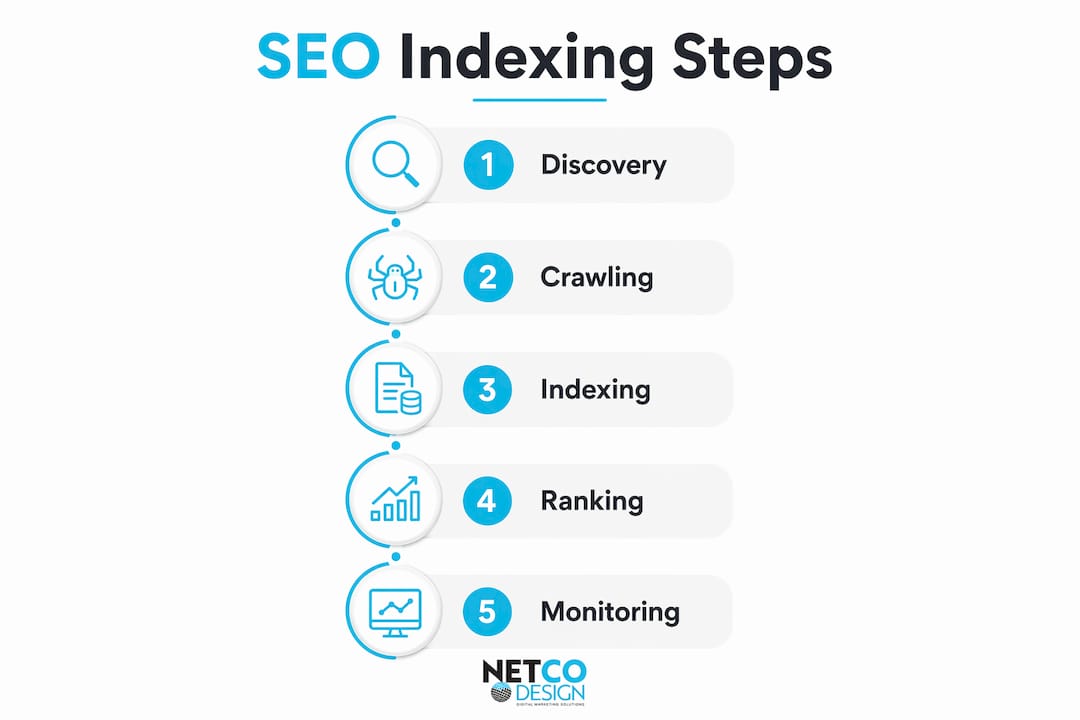
The full process moves through four stages: discovery, crawling, indexing, and ranking. Discovery happens when Google finds a URL through a sitemap, a backlink, or an internal link. Crawling is when Googlebot visits the page and reads its content. Indexing is when Google decides the page is worth storing. Ranking is the final step, where stored pages compete for positions in search results.
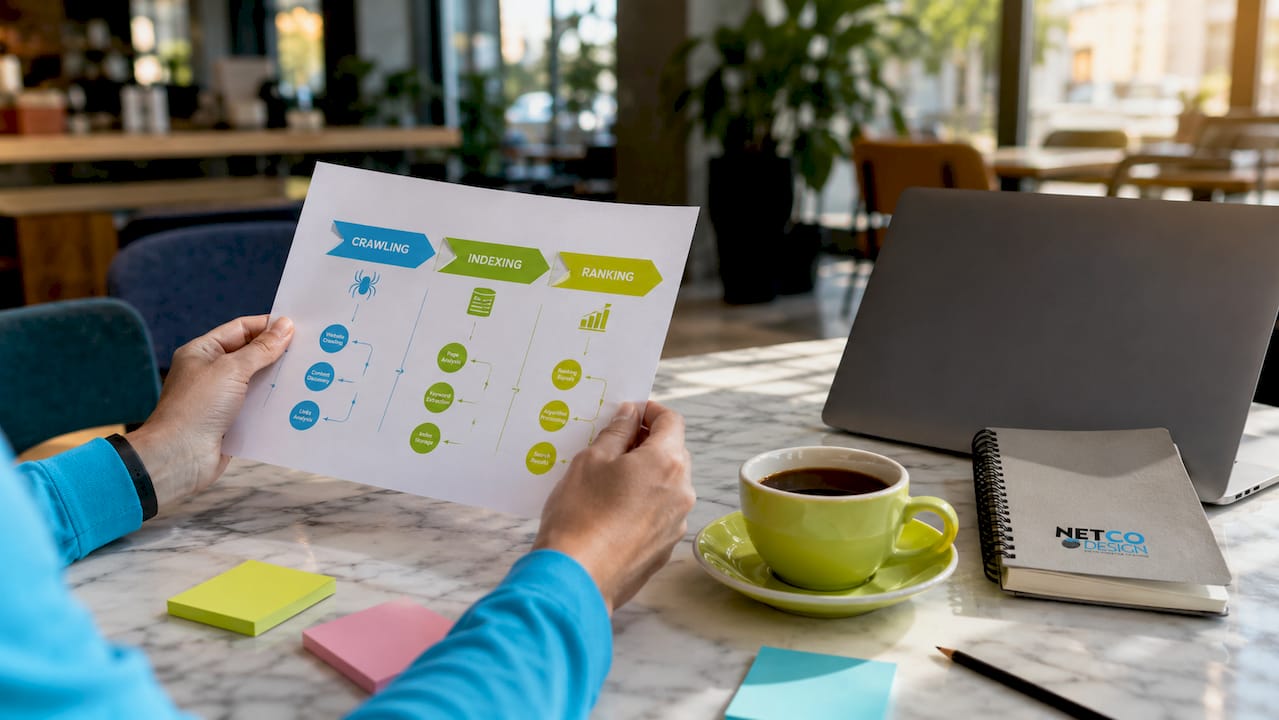
During indexing, search engines evaluate several signals to decide whether a page earns a spot in the database. Indexing stores metadata about pages, including words and their locations, but not full page copies. That distinction matters because it explains why two pages with identical text create a duplicate problem.
Key signals Google evaluates during the indexing stage include:
- Content quality: Thin, vague, or copied content fails the quality threshold.
- Canonical URLs: Google uses canonical tags to identify the preferred version of a page and avoids indexing duplicates.
- Accessibility: Pages blocked by robots.txt or requiring a login cannot be crawled or indexed.
- Mobile compatibility: Google’s mobile-first approach means the mobile version of your content is what gets evaluated.
- Page relevance: Content must clearly match a topic and demonstrate value to a real user.
Pro Tip: Use the URL Inspection tool in Google Search Console to check whether a specific page is indexed and to see exactly how Google renders it.
Why do some pages fail to get indexed?
Pages fail to get indexed for two main reasons: technical blockers and content quality issues. Both are fixable, but you need to know which one applies before you act.
Technical blockers are the most common culprits. A noindex meta tag tells Google to skip the page entirely. A disallow rule in your robots.txt file prevents Googlebot from even visiting. Robots meta tags, canonical URLs, and sitemap updates are key technical factors affecting indexing status. Proper canonicalization consolidates signals and prevents duplicate indexing.
Content quality issues are trickier because they require editorial judgment. Search engines apply a dynamic quality threshold to index pages, which varies based on topic relevance and domain authority. A page that ranks well on a high-authority site might not get indexed at all on a newer domain with the same content. Non-indexed pages often need content improvements, not just technical fixes.
Common reasons pages get excluded from the index include:
- Thin content: Pages with very little original text or value.
- Duplicate content: Multiple URLs serving the same or nearly identical content.
- Noindex directives: Tags intentionally or accidentally blocking indexing.
- Crawl budget waste: Large sites where Googlebot runs out of crawl budget before reaching important pages.
- Mobile content gaps: Mobile-first indexing means discrepancies between desktop and mobile content can cause indexing problems.
Google Search Console flags affected pages under the “Crawled, currently not indexed” status. That label tells you Google visited the page but chose not to include it. The fix is almost always a content improvement, not a technical patch.
Pro Tip: If Google Search Console shows a page as “Crawled, currently not indexed,” rewrite the page to add depth, original analysis, or unique data before requesting a re-index.
How to check and speed up indexing
Verifying your indexing status and improving it does not require advanced technical skills. It requires the right tools and a clear process.
-
Open Google Search Console and check Index Coverage. The Coverage report shows which pages are indexed, which are excluded, and why. Filter by “Excluded” to find pages with issues. Google Search Console provides Index Coverage reports that identify indexing status and issues like “Crawled, currently not indexed” pages.
-
Submit an XML sitemap. A sitemap tells Google which pages exist and how often they update. Submit it through Google Search Console under the Sitemaps section. Submitting sitemaps can expedite indexing, especially for sites with frequent content updates.
-
Use the URL Inspection tool for individual pages. After publishing or updating a page, paste the URL into the inspection tool and click “Request Indexing.” This signals Google to prioritize that URL in its next crawl.
-
Strengthen your internal linking structure. Internal linking and backlinks from authoritative sites enhance discovery and can help indexing speed. Pages buried deep in your site with no internal links are harder for Googlebot to find and index.
-
Improve crawl budget efficiency. Large sites waste crawl budget on low-value pages like filtered product pages, session ID URLs, or outdated content. Block these with robots.txt or noindex tags so Googlebot focuses on pages that matter.
-
Earn backlinks from credible sources. External links from established sites signal to Google that your content is worth discovering and indexing. A strong domain authority profile accelerates this process.
-
Audit your content for quality. Every page you want indexed should answer a specific question, provide original value, and meet a minimum length that fully covers the topic. Review the criteria for a well-optimized page to make sure your content clears the quality bar.
Following these steps consistently produces faster and more reliable indexing results than any single technical fix.
Indexing vs. crawling vs. ranking: what is the real difference?
Indexing, crawling, and ranking are three separate stages, and confusing them leads to wasted effort. Each stage has a distinct purpose and a different set of factors that influence it.
Crawling is discovery. Googlebot visits a URL and reads its content. Crawling does not guarantee indexing. Indexing is acceptance. Google evaluates the crawled page and decides whether to store it in its database. Indexing must precede ranking. An unindexed page cannot rank in search results, period. Ranking is positioning. Once a page is indexed, it competes against other indexed pages for positions in search results based on hundreds of signals.
Think of it this way: crawling is the application, indexing is the acceptance letter, and ranking is where you place in the class. You cannot skip steps.
The distinction between indexing and ranking matters because the fixes are completely different:
- Indexing problems are solved by improving content quality, fixing technical blockers, and submitting sitemaps.
- Ranking problems are solved by building authority, earning backlinks, improving user experience, and refining content relevance.
Ranking involves hundreds of factors beyond indexing, including topical relevance and user experience. Indexing is the entry checkpoint. Sites cannot rank without being indexed, but being indexed alone does not ensure a high ranking. A page can sit in Google’s index for years without ever appearing on page one. That is a ranking problem, not an indexing problem. Knowing the difference saves you from applying the wrong solution.
Key Takeaways
Indexing is the entry checkpoint for search visibility. A page must be indexed before it can rank, but indexing alone does not guarantee a strong position in search results.
- Indexing vs. crawling: Crawling discovers pages; indexing stores them. Not every crawled page gets indexed.
- Quality threshold: Search engines reject thin, duplicate, or inaccessible content from the index, regardless of domain size.
- Mobile-first indexing: Google evaluates the mobile version of your content first, so mobile gaps directly affect indexing.
- Google Search Console: The Index Coverage report and URL Inspection tool are the fastest ways to diagnose and fix indexing issues.
- Indexing vs. ranking: Indexing is eligibility; ranking is position. Fixing one does not automatically fix the other.
Why indexing is the most overlooked part of SEO
Most website owners I work with focus almost entirely on keywords and backlinks. They publish content, build a few links, and then wonder why their pages are not showing up. The answer, more often than not, is that the pages were never indexed in the first place.
The mistake I see most frequently is treating indexing as automatic. It is not. Google makes a deliberate decision about every URL it crawls. If your content does not clear the quality threshold, Google simply moves on. I have seen well-written pages sit in the “Crawled, currently not indexed” bucket for months because the site had too many thin supporting pages diluting its overall quality signal.
The second mistake is confusing an indexing problem with a ranking problem. A client once spent three months building backlinks to a page that had a noindex tag on it. Every link was wasted. A five-minute check in Google Search Console would have caught it immediately.
My strongest advice is to build indexing checks into your publishing workflow from day one. Before you promote any new page, verify it is indexed. Set a monthly reminder to review your Index Coverage report. Treat indexing as a maintenance task, not a one-time setup. The sites that rank consistently are the ones where someone is watching the index closely, not just the keyword rankings.
— Lori Piencykoski
How Netco Design supports your SEO and indexing goals
Getting your pages indexed correctly is foundational to everything else in SEO. Netco Design works with website owners and marketing teams across Tampa Bay and beyond to identify indexing gaps, fix technical blockers, and build content strategies that clear Google’s quality threshold.
The team at Netco Design conducts full technical SEO audits, including Index Coverage analysis, sitemap reviews, and mobile-first compatibility checks. If your site has pages stuck in the “not indexed” bucket, that is exactly the kind of problem Netco Design solves. For a broader view of where search is heading and how indexing fits into the bigger picture, the 2025 SEO trends guide is a strong starting point. You can also explore the full SEO checklist for new websites to make sure your site is set up for indexing success from launch.
FAQ
What does indexing mean in SEO?
Indexing in SEO is the process where a search engine stores and organizes a web page in its database after crawling it. Only indexed pages are eligible to appear in search results.
What is the difference between crawling and indexing?
Crawling is when a search engine visits and reads a page. Indexing is when the search engine decides to store that page in its database. Crawling does not guarantee indexing.
Why is my page crawled but not indexed?
Google flags pages as “Crawled, currently not indexed” when they fail its quality threshold. The most common causes are thin content, duplicate content, and noindex tags.
How do I get my pages indexed faster?
Submit an XML sitemap through Google Search Console, use the URL Inspection tool to request indexing, strengthen internal links, and improve content quality. These steps consistently speed up the indexing process.
Does being indexed mean my page will rank?
No. Indexing is eligibility, not position. A page must be indexed before it can rank, but ranking depends on hundreds of additional factors including content relevance, backlinks, and user experience signals.

